OpenAI 的 FDE 团队:让自己原来的工作变得不再有必要,恰恰说明 FDE 做对了
从芯片验证到语音客服,前线部署工程师先把客户的问题做成,再把经验沉淀为更好用的产品和更强的模型。

OpenAI 有一支专门与企业客户一起做项目的工程团队,叫 FDE,也就是前线部署工程师。他们要把模型接进客户的实际工作,做出员工能够可靠使用的系统。
这件事有多费劲?在一家大型半导体客户的项目里,AI 要帮工程师生成芯片测试、分析故障原因、辅助理解架构。生成的测试有没有用,找出的故障原因对不对,都需要和客户的芯片工程师一起检验。团队还得接入工具、组织模型执行任务,为不同用例搭建配套系统。
OpenAI 投入了约 15 名 FDE,推进 10 多个用例。有些成员此前没有半导体经验,只能一边进入客户团队工作,一边学习芯片设计。经过最初 3—6 个月,这些用例才全部进入生产,并获得早期用户采用。一些原本需要数周的调试工作,也被压缩到了数小时。
但 Codex 的进步,给这群刚把事情做成的工程师带来了一个新问题:如果 Codex 已经能轻松完成我们花了几个月才搭好的用例,我们接下来做什么?
他们确实开始用更成熟的 Codex 接替原有实现,把各自开发的应用迁到共用框架,最终移除了相关项目约 90% 的定制代码。
在团队负责人 Colin Jarvis 看来,让自己原来的工作变得不再必要,恰恰说明 FDE 做对了。一支工程团队,为什么会把替代自己辛苦搭建的系统,当成成功?
部署鸿沟:模型会做,为什么企业还用不稳?
模型能力的进步,比把能力用进工作的系统和流程更快。一个模型在基准测试里表现很好,进入真实业务后,却未必能应付各种变量和约束。模型看起来能做什么,与人们能够可靠地用它完成什么工作之间的距离,OpenAI 称为“部署鸿沟”。
农业机械公司约翰迪尔(John Deere)的例子很直观。它的 See & Spray 精准除草技术,利用摄像头和机器学习识别杂草,只向需要的位置喷洒,化学品使用量最高可减少 70%。但要获得这些收益,农户还得会配置设备、规划种植季,并随条件变化调整作业方式。
约翰迪尔使用 OpenAI API,把个性化支持提供给更多农户:用自然语言回答问题,给出适合具体情况的设置建议,识别设备是否没有充分发挥潜力,并帮助农户理解技术带来的价值。精准喷洒技术负责减少无差别用药,AI 支持服务则帮助人把技术用好。
这种工作没有统一的现成手册。有时,连判断结果对不对的标准答案都需要与客户一起建立。FDE 要先弄清业务结果是什么,再判断阻碍来自应用系统,还是模型本身尚不能完成任务。
结果优先:先在现场做成,再让成功可以复制
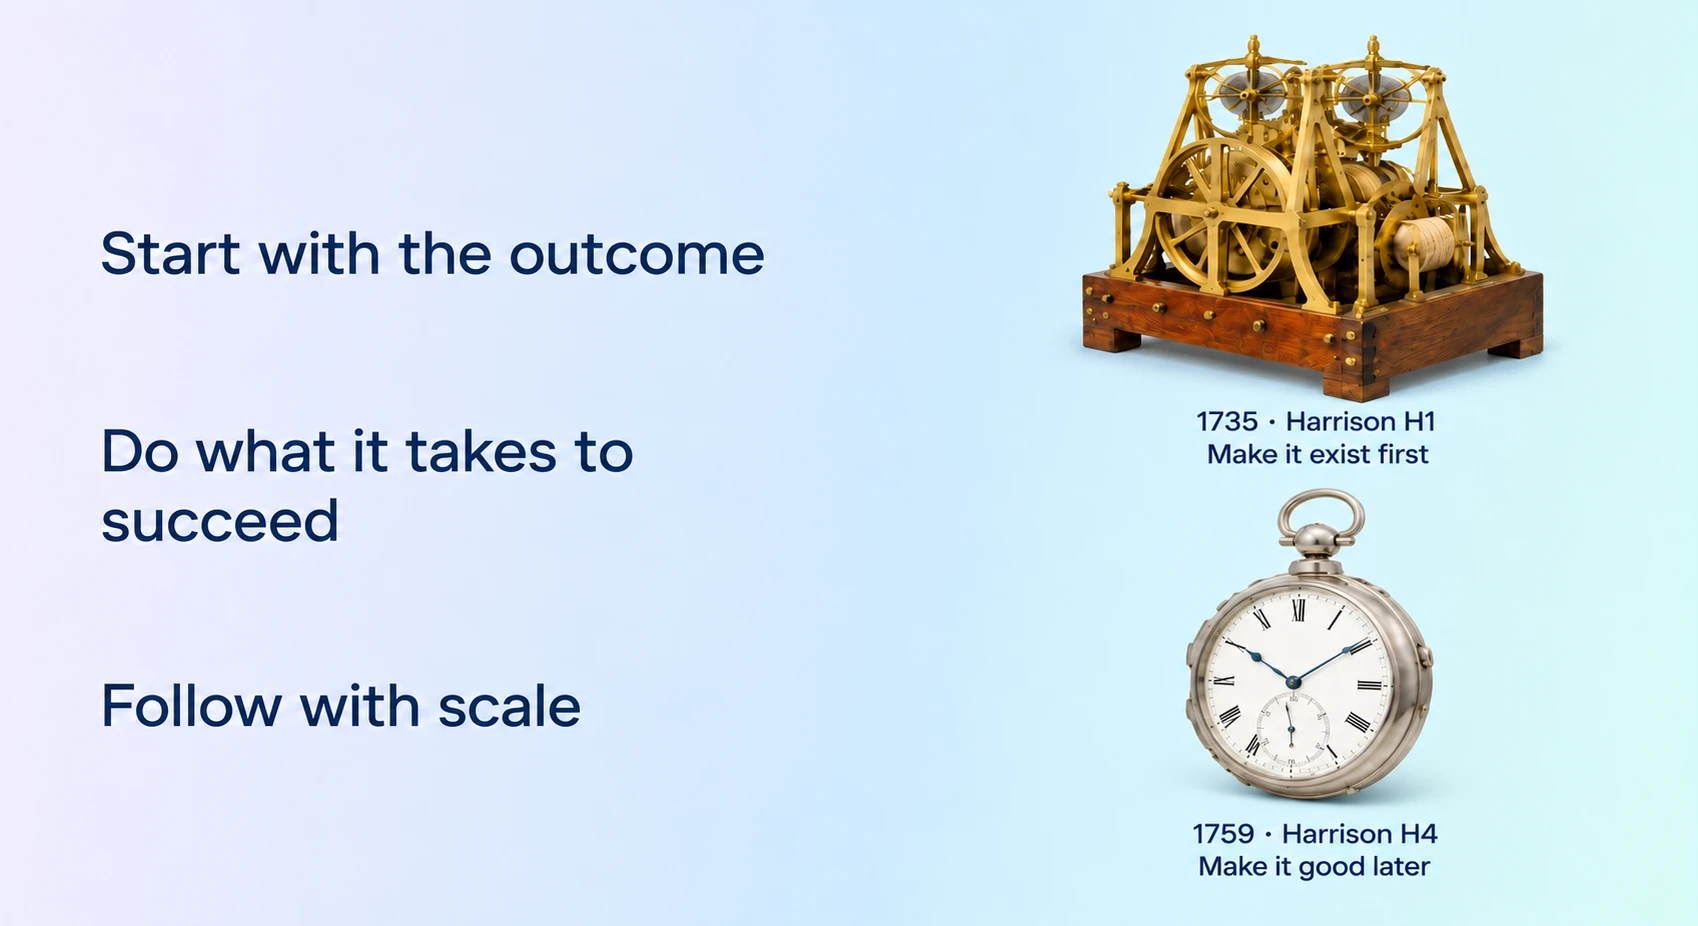
Jarvis 给团队的原则是:从结果出发,完成做成它所需的工作,再把成功推广开来。

OpenAI 用两代 Harrison 航海钟表达这一顺序:先做成,再改进。图中的钟表是工程类比。
芯片验证要检查设计是否按预期工作,可能占一个项目约 70% 的工作量,因此这里哪怕只省下一部分时间,也有实际价值。
团队与客户共同建立业务评估(Evals),用具体任务检验 AI 是否完成工作,而不只看回答像不像那么回事。
为各用例搭建的执行框架(Harness),负责组织模型运行、工具调用和结果处理。OpenAI 还披露了两项结果:
- AI 定向测试生成节省约 48% 的时间。
- 计算内核优化带来的性能提升中位数为 22%。(计算内核是执行特定计算任务的底层代码)
团队会混合配置通才与领域专家。在生命科学项目里,具有科学背景的 FDE 能与研究人员讨论临床前的靶点验证和优先排序、基因表达分析、化学合成路线重建,并据此判断工作流程可以怎样改进。快速学习和专业判断都需要有人承担。
架构重构:为什么要删掉约 90% 的定制代码?
用例已经产生价值,扩展却仍然困难:每个工作流都需要较多定制集成,推广到另一支团队时,部署和维护还有很多工作要做。

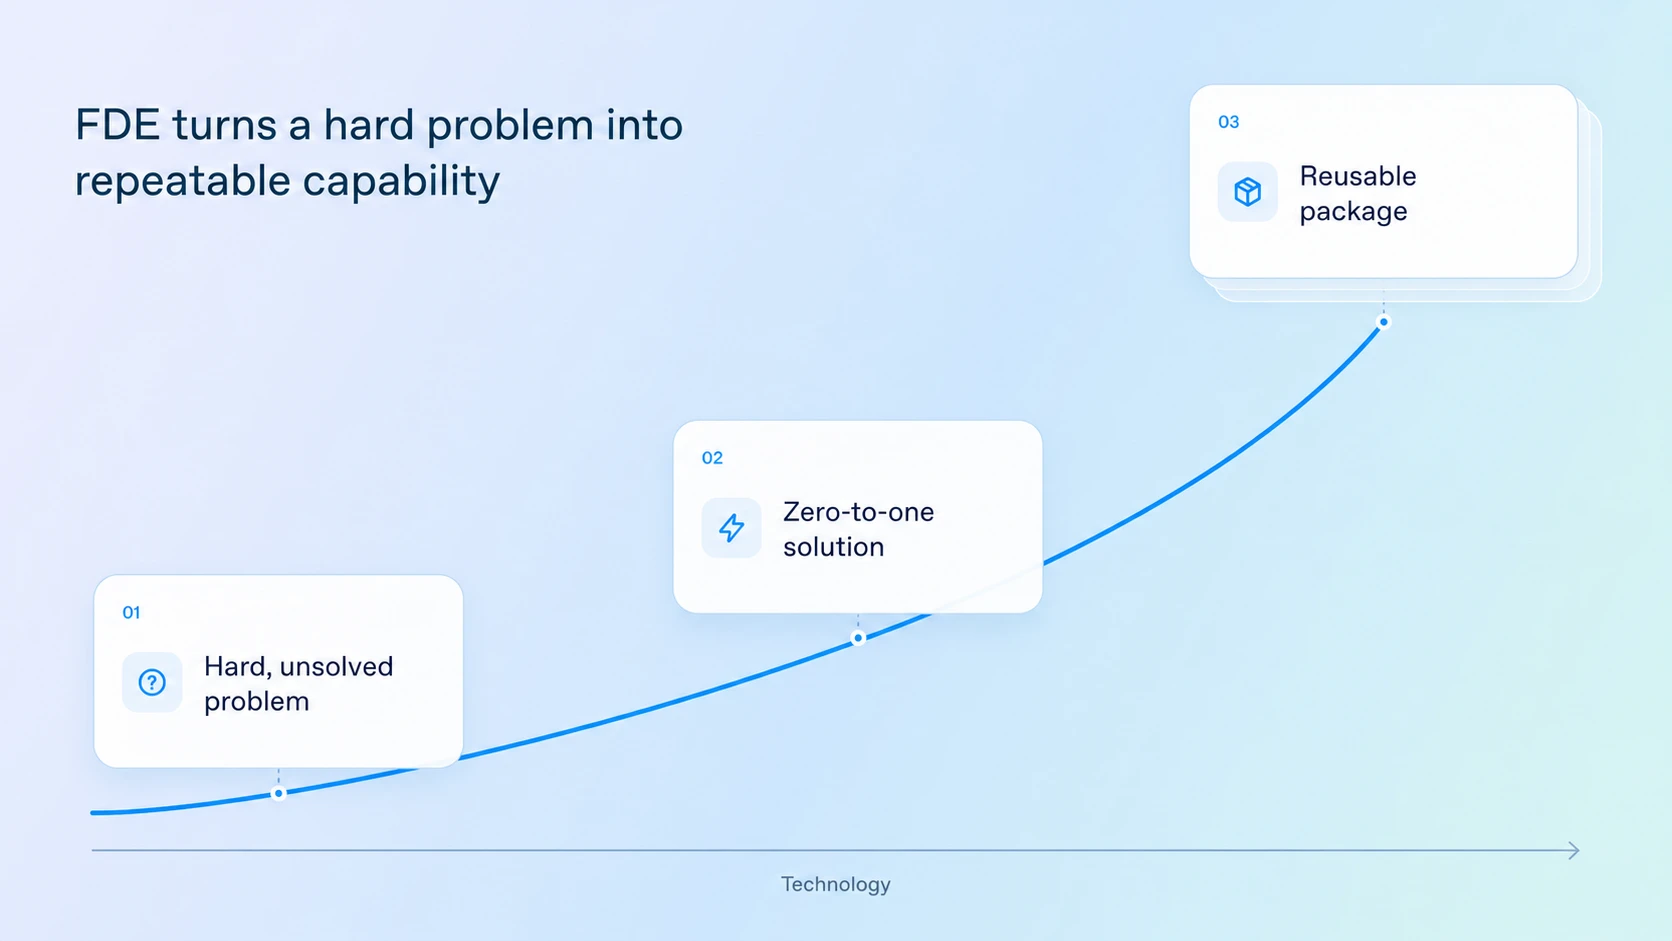
三个节点依次是未解难题、从零到一的方案、可复用包。这是定性演进示意,曲线不代表量化增长率。
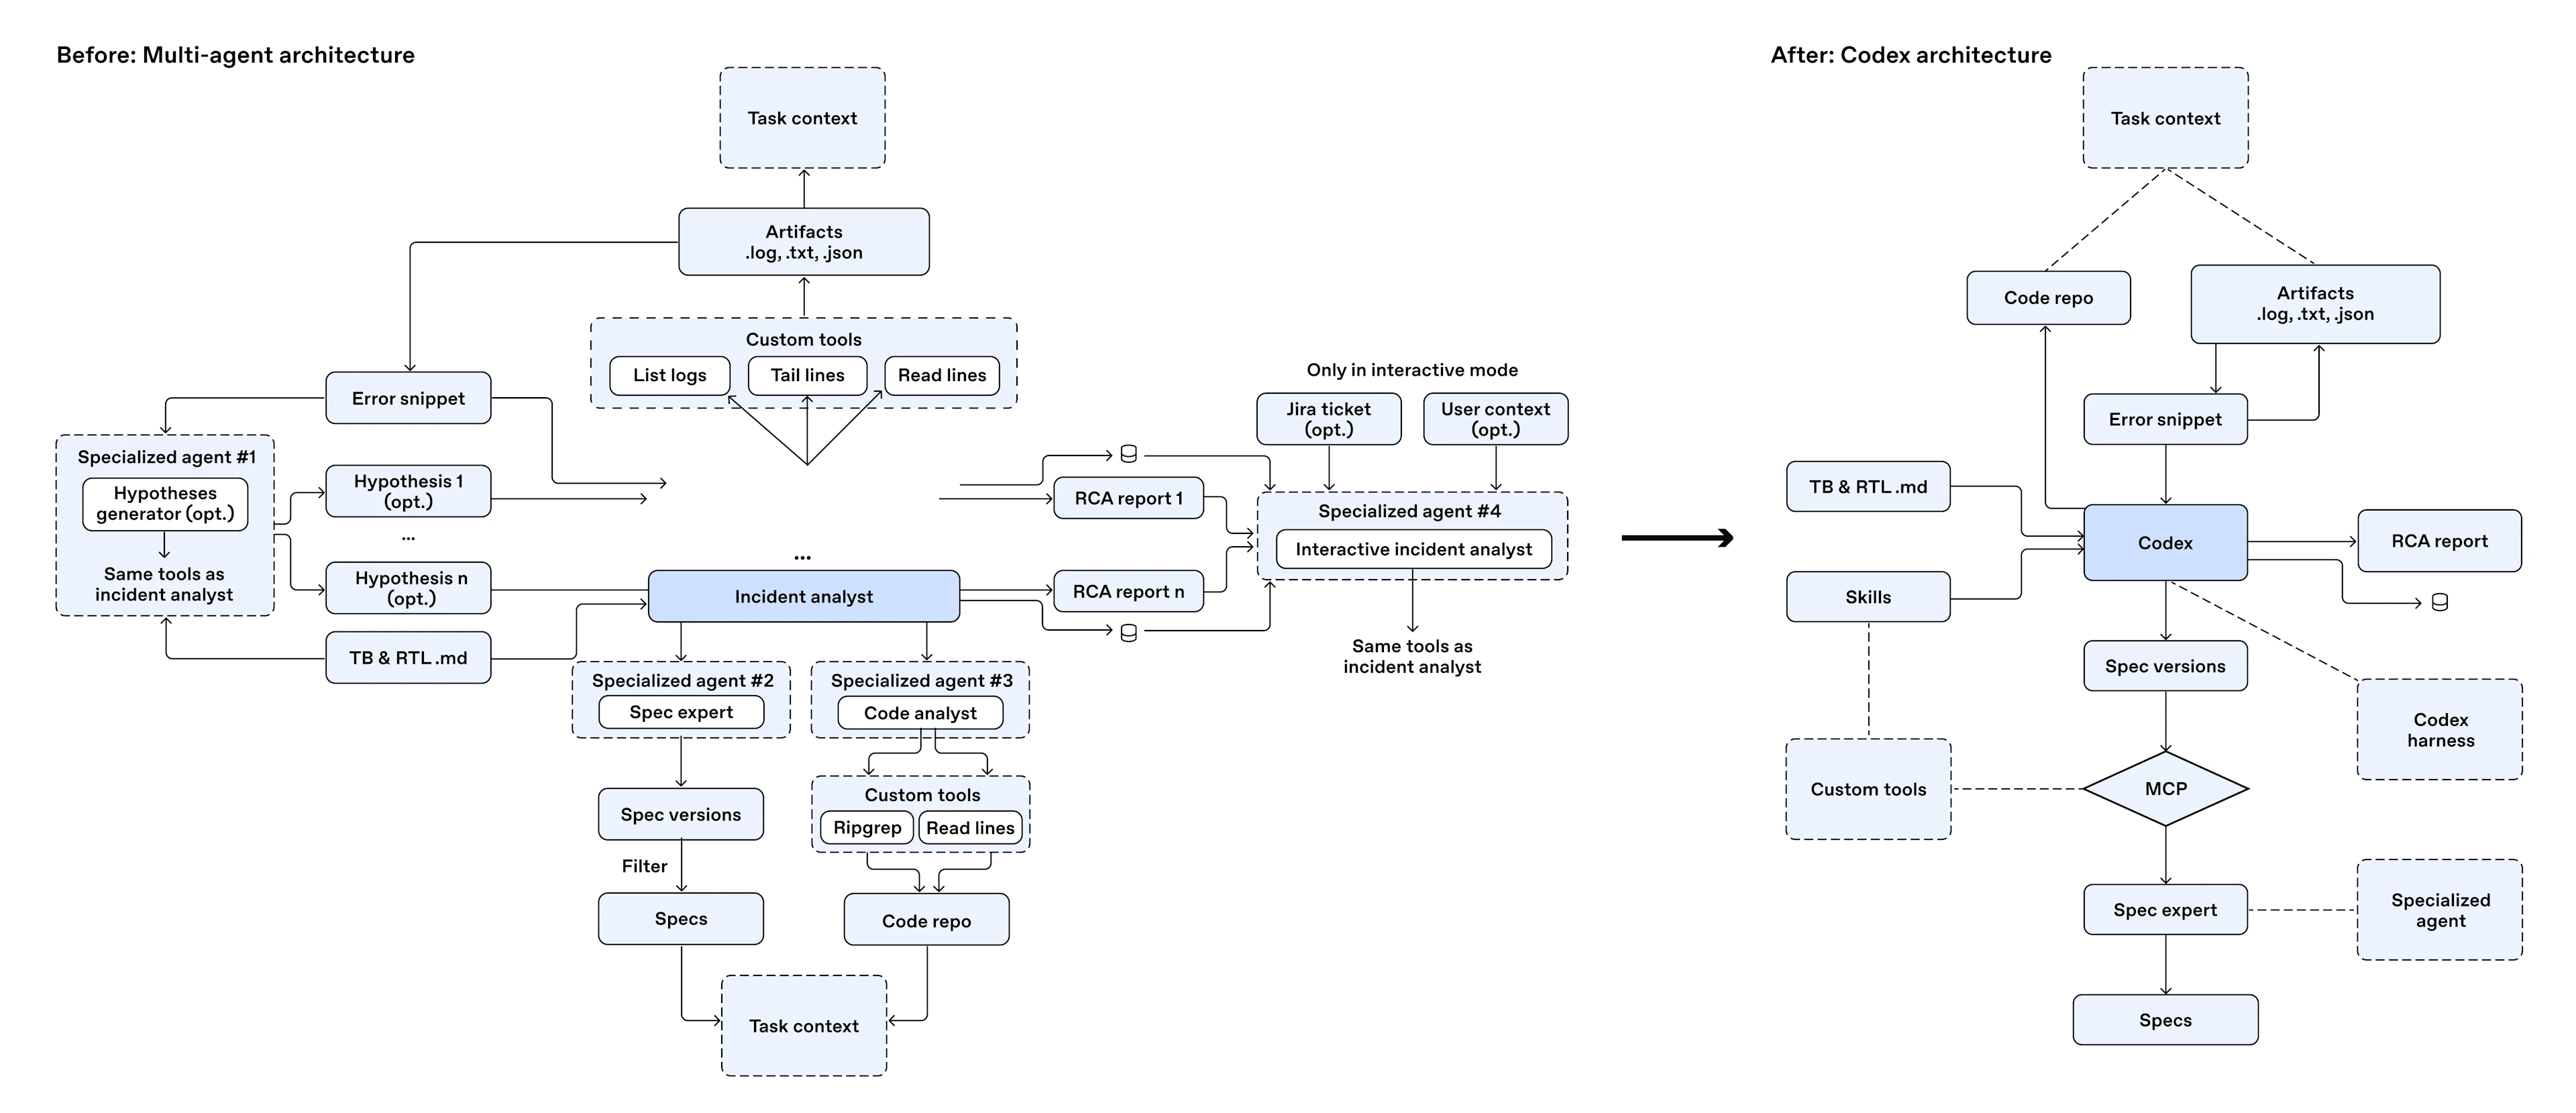
原文的根因分析架构图展示了当时的复杂度:提出假设的 Agent、事故分析角色、规范专家、代码分析角色和交互式分析角色共同处理日志、规范与代码,各处还连着专用工具。团队也为不同用例写了各自的终端界面和命令行入口。
随着 Codex 能力增强,一名 FDE 尝试围绕它重建应用,随后团队把用例迁到以 Codex 为核心的共同执行框架。Codex 既承担共用的运行能力,也成为使用入口,原来各自编写的终端 UI 和 CLI 得以退役。

左侧为多个分析角色与定制工具的协作,右侧保留代码库、任务产物、Skills,以及通过 MCP 接入的工具和规范专家。约 90% 的代码减少来自正文披露,不能按图中节点数计算。
查看原尺寸图 ↗
定制应用被拆成共用底座上的插件和 Skills:可反复使用的工作方法封装为技能,相应功能通过插件提供。客户内部的 AI 卓越中心(CoE,也就是集中管理企业 AI 能力的团队)可以统一管理和分享这些能力。
MCP 是把外部工具接入模型应用的一种连接协议。图里的专用工具和规范专家仍通过它参与工作;代码库与任务产物也仍是 Codex 的输入。架构简化,并不意味着行业知识、专用工具或所有专家 Agent 都消失了。
Codex 的集中改进也能惠及这些用例,团队需要分别维护的连接代码随之减少。
扩展时仍要接入新团队需要的系统、建立符合其任务的新评估。原文给出一个用例:首次部署花了两个月,扩展至第二个团队花了一天。它展示了复用的价值,但不是所有后续项目一天上线的保证。
同一项根因分析工作,哪些实现被接走了?
左右都要读取任务资料、分析故障并输出报告;变化在于由谁组织这些工作。
组织假设与分析流程
专用日志工具 · 规范 · 代码库
MCP 连接专用工具与规范专家
代码库与任务产物仍是输入
共用 Codex 接手入口和执行底座,让各用例不必分别维护这些实现;底座改进一次,各用例都能受益。
团队最初为生产环境付出的工作并没有白费:它们帮助团队确认哪些行为有用、哪些要求必须满足。产品进步以后,定制实现可以被替换,已经确认的价值则继续交付给用户。
应用系统还没做好,还是模型本身还不会?
原文描述了两种工作方向。模型已经能完成任务时,FDE 与客户、产品团队一起,让方案更容易部署和复用;模型还做不到时,则与客户和研究团队共同明确能力差距,再持续改进。这两种工作可能交织在一个项目里。
从一次次现场部署中提炼可复用能力
OpenAI 的企业语音与聊天 Agent 产品 Presence,就来自现场经验的积累。相关工作从 Swarm 发展到 Agents API,再沉淀进 Presence:团队在实际部署中辨认哪些问题需要定制、哪些基础模块值得供更多团队使用,让后来的开发者不必重建同样的基础设施。OpenAI 还披露,一家客户已经用 AI 处理超过半数来电。
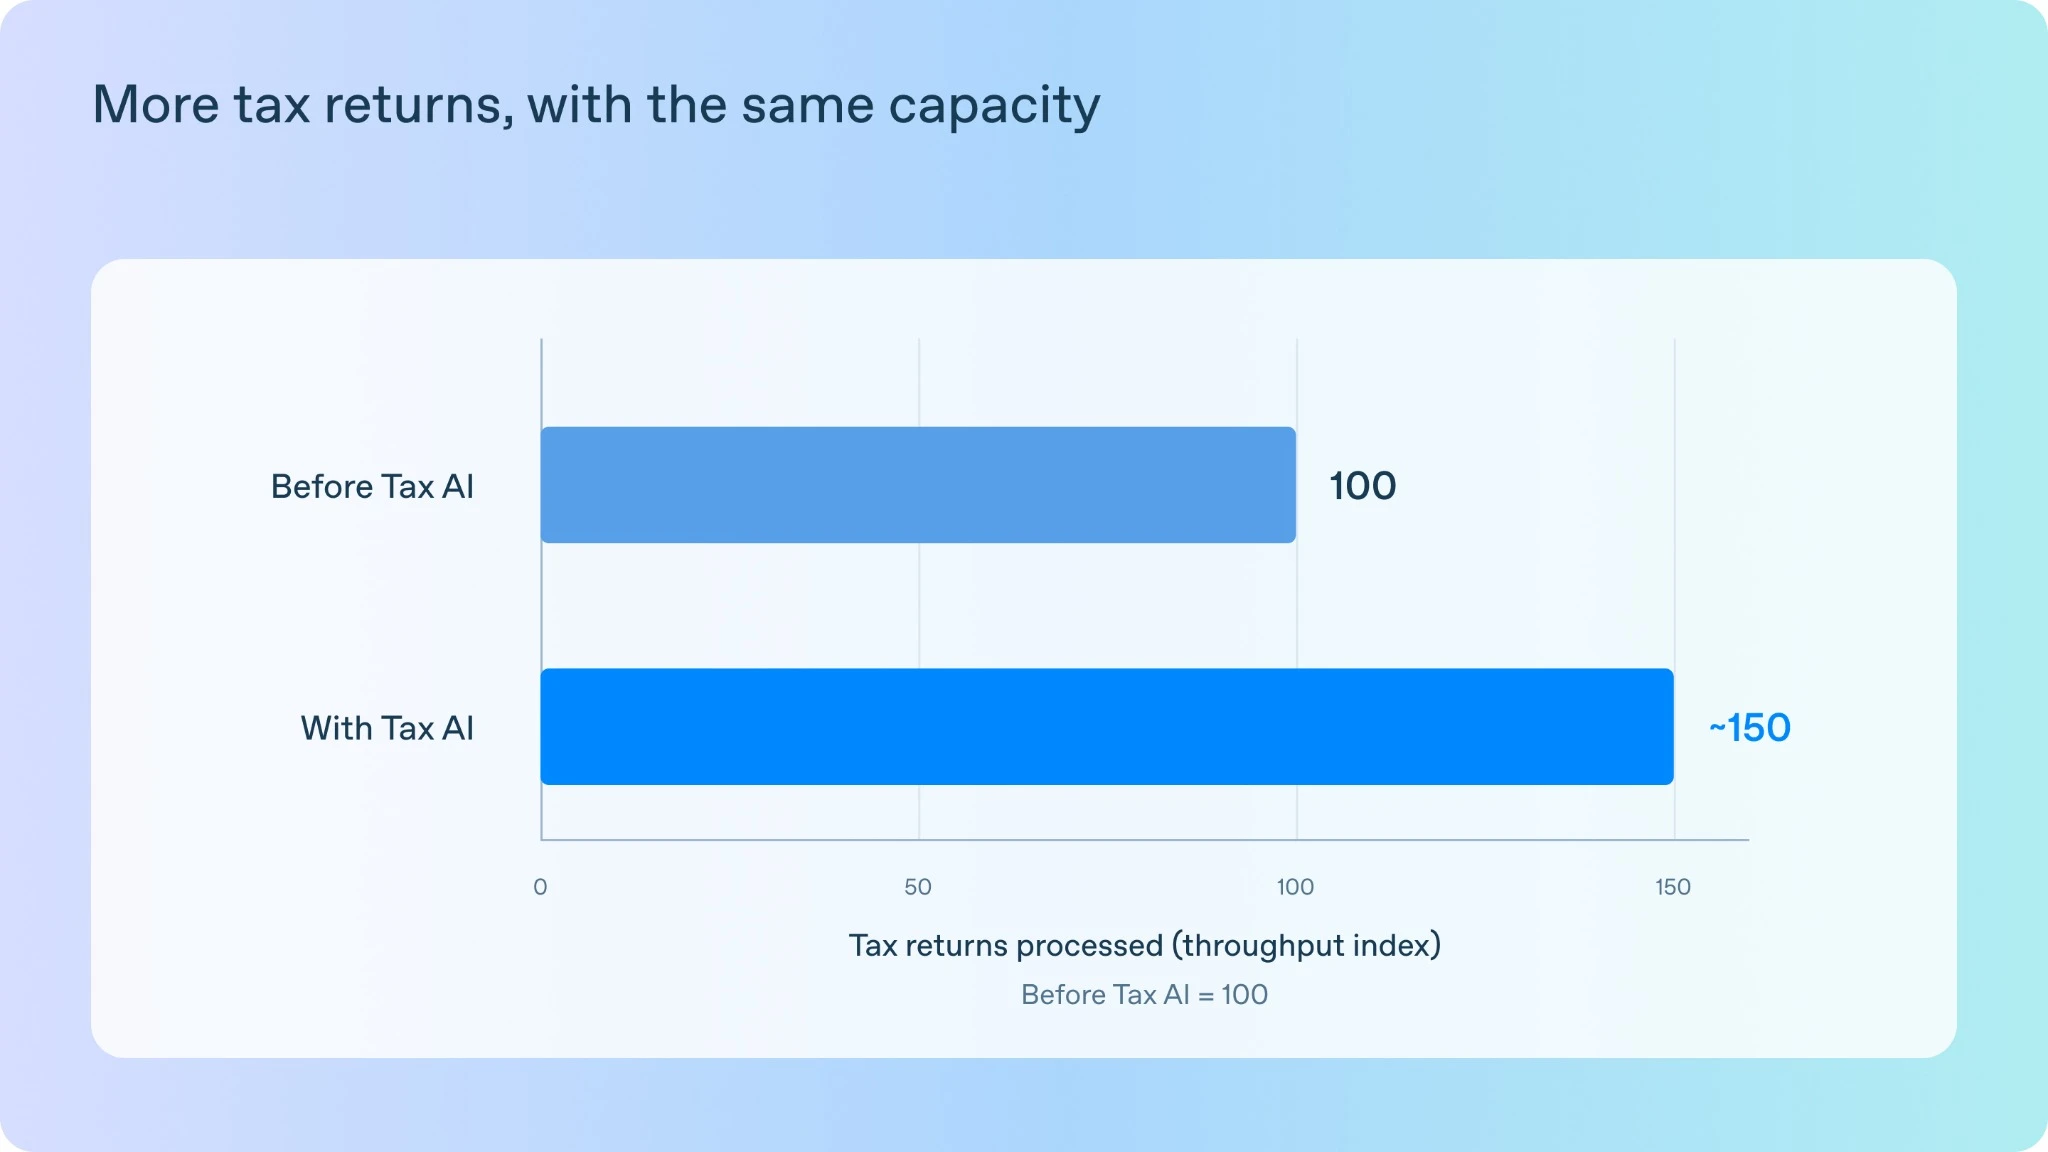
Thrive Holdings 与旗下 Crete 会计事务所的 Tax AI 项目,也展示了专业实践怎样变成可复用的方法。OpenAI 的 FDE 和研究人员与工程师、会计师共同建设系统。试点中,Tax AI 处理了 7,000 份报税表,吞吐量提高约 50%。

100 和 150 是归一化指数,不是实际税表份数;7,000 份是试点处理量。
其中,租赁房产申报花了六周的工程工作与从业者复核,才达到 90% 的精确率和召回率。精确率关注系统判出的结果有多少正确,召回率关注应当找出的结果有没有漏掉。原文没有展开这项评估按哪些具体字段或判断计分,因此不能把 90% 理解为同样比例的整份税表可以无人处理。
攻克这一任务形成的可复用模式,让团队更容易扩展到其他复杂税务附表。团队目前还在把同样的方法用于记账、审计与 IT 支持。这个案例说明了工程与专业反馈的共同作用,不能仅凭这些信息把问题全归为产品或模型其中一类。
真实业务评估也能把模型短板送到研究团队面前
Jarvis 认为,如果只做现有模型已经能完成的任务,就难以发现研究团队接下来该补齐哪些能力。因此,不少重要合作会从模型暂时做不到的难题出发,由客户、FDE 和研究团队一起推进。
另一家大型电信客户已经有了客服平台,希望进一步扩展到语音。语音约占它客服量的 90%,却带来口音、语调、延迟与准确性等生产要求。
在项目范围界定阶段,模型在关键评估上的表现约为 60%,函数调用和指令遵循需要改进。函数调用,就是让模型在需要时调用完成业务所需的工具;如果这一步不可靠,即使对话听起来流畅,也可能办不成客户的事。
FDE 向客户说明了能力差距,并把研究团队引入项目。客户愿意共同推进尚未解决的问题;FDE 建设平台、定义模型需要完成的任务并推动交付;研究团队改进模型,提供连续的新快照,让团队按客户要求测试进展。
经过六个月,关键评估表现从约 60% 提升到 80%,再达到 90% 以上,满足了生产要求。形成的语音模型既支持这位客户,也用于其他定制客服部署和 Presence 的托管部署。

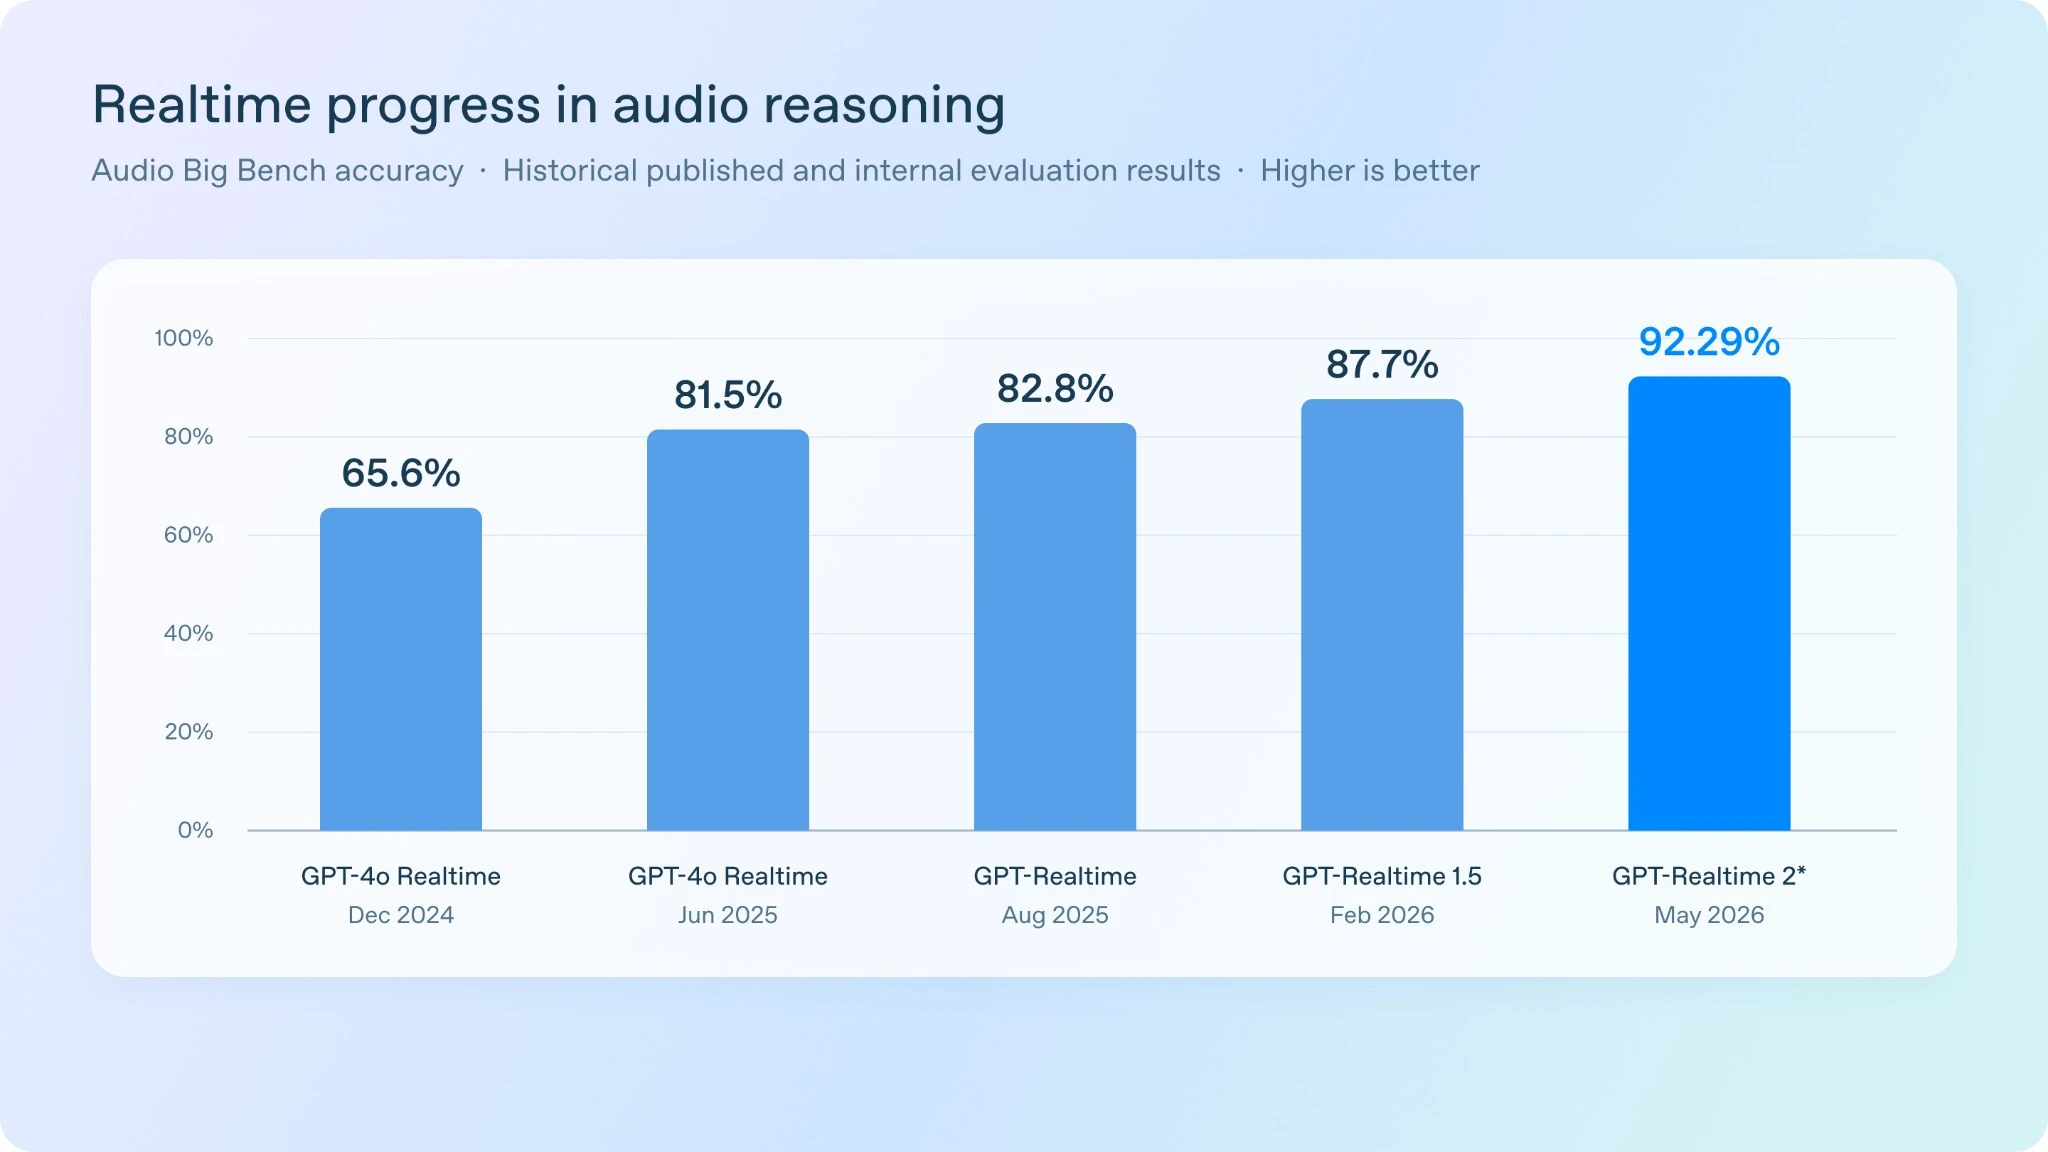
五个版本准确率依次为 65.6%、81.5%、82.8%、87.7% 和 92.29%;图中覆盖约 17 个月,客户案例则是六个月的关键业务评估。图的最后一柱带星号,原图未展开解释。
这里,现场交付还承担了另一项作用:把“模型还不够好”具体化成能够测试、能够反复检验的问题。研究进步再回到现场接受验证,一位客户遇到的困难,也可能帮助后来的客户少走一段路。
同样是落地卡住,工作会走向哪里?
这两条路径归纳自原文案例,可同时发生;它们不是一份穷尽问题的诊断标准。
让方案更容易部署与复用
FDE 与客户、产品团队提炼共用模块,减少重复集成,让下一个团队从已有能力起步。
明确差距,和研究团队共同改进
FDE 建平台、定义任务,Research 改进模型,再以新的模型快照接受客户要求的检验。
芯片扩展案例补充:原文一个用例首次部署花两个月,扩展至第二团队花一天;新团队仍要接入所需系统并建立评估。
何时需要 FDE?还要看客户能力与复用基础
OpenAI 的案例同时覆盖了“模型已能做,但方案还难部署”和“模型还达不到要求”的工作。不能把共同研发的一个案例,变成所有 FDE 项目都必须从模型能力边界起步的条件。
如果要判断自己的企业是否需要这支团队,还要看客户能否独立完成实施,以及现场做出的模块能否被其他客户复用。站内的 FDE 选型解读进一步讨论了这两个问题。
当产品接替了定制实现,继续找更难的问题
Jarvis 倾向于在多数大语言模型开发中选择更简单的解决方案。前提始终是,它能可靠地解决现场的问题。系统的复杂度,应当由任务需要来决定。
每一次合作,都应当给后来的工作留下更好的起点:一种更容易部署的产品,一项能处理更难任务的模型能力,或者更少需要重复完成的定制工程。
因此,当 Codex 能承担原来花数月搭建的用例时,团队不必守住旧实现来证明价值。把已经验证的结果保留下来,让通用产品接手它能够承担的部分,再去解决下一个更难的问题。
延伸观看:OpenAI FDE 团队官方访谈回放,讨论团队日常、客户反馈如何影响产品,以及适合这个岗位的能力。官方页面需登录观看。
OpenAI 的 FDE 团队:让自己原来的工作变得不再有必要,恰恰说明 FDE 做对了
模型表现与可靠使用之间,还隔着什么?
OpenAI 的前线部署工程师(FDE)与企业客户一起,把模型接进真实工作,做出员工能可靠使用的系统。难点在于:模型在基准测试里表现很好,进入业务后,未必能应付各种变量和约束。
模型看起来能做什么,与人们能够可靠地用它完成什么工作之间的距离,OpenAI 称为“部署鸿沟”。
Codex 接手什么,行业工作留下什么?
一家半导体客户要用 AI 生成芯片测试、分析故障。约 15 名 FDE 推进 10 多个用例,一边学行业,一边与客户检验结果;最初 3—6 个月,用例进入生产并获得早期用户采用。
随后 Codex 能力增强,团队将用例迁到以 Codex 为核心的共用执行框架,移除了相关项目约 90% 的定制代码。被替换的是实现,已验证的业务价值继续交付。
原文一个用例首次部署花两个月,扩展至第二团队花一天。这是首次部署与复用扩展的对比;新团队仍要接系统、建评估。前期工程的价值,是探明哪些行为有用、哪些要求必须满足,让后续团队有更好的起点。
一次现场项目,怎样改进产品与模型?
现场遇到困难,要辨认应用系统与模型能力各自的缺口。两条工作路径可以交织,目标都是让后来的客户少做重复工程。
FDE 与客户、产品团队提炼共用模块。Swarm → Agents API → Presence 的演进,就沉淀了现场语音与聊天 Agent 的部署经验。
电信客户的语音客服中,函数调用与指令遵循需要提升。客户承诺共同探索,FDE 建平台、定义任务,研究团队改模型;六个月内关键业务评估约 60% → 80% → 90% 以上。
评估口径要分开:上面的 60% → 90% 以上,是电信客户六个月的业务评估;原文另有 Audio Big Bench 五个版本的历史成绩(65.6% → 92.29%,约 17 个月),不是同一条项目曲线。
什么时候值得让 FDE 进场?
判断自己的企业是否需要 FDE,还要看客户能否独立实施,以及现场做出的模块能否被其他客户复用。很多合作会主动挑战模型边界,但这不是所有 FDE 项目都必须满足的起点。
What FDE means at OpenAI
What forward deployed engineering means at OpenAI
When Codex came out, someone on the team asked me, “What do we do when Codex can just one-shot the use cases we spent the last few months building?”
That question gets to the heart of what FDE means at OpenAI. We work alongside customers to understand their hardest problems and build solutions they can depend on. What we learn helps shape our products and gives Research concrete problems to solve.
That is progress. If we make ourselves obsolete every couple of months, our FDE team is doing its job.
I founded the team in early 2025 to close what we call “the deployment gap”: the distance between what models appear capable of and what people can reliably use to do their work.
Model capabilities have moved faster than the systems and processes needed to put them to use. Sometimes the missing piece is a product. Sometimes a model performs well on a benchmark but cannot do the job with real-life variables and constraints.
We focus on customers’ hardest problems. Where our models can do the job today, we work with Product and our customer to make the solution repeatable and, where they fall short, we work with customers and Research to define the gap and make improvements. Our goal is for each engagement to leave the next customer with a better starting point—if we raise the floor to the point our customers don’t need FDEs to solve this class of problem the next time, we have done our job well.
The challenge for John Deere, a 200 year-old agriculture business, was how to scale personalized advice for farmers.
One example is See & Spray, its precision weed-control technology, which uses cameras and machine learning to identify and spray weeds rather than treating entire fields to reduce chemical use by up to 70%.
But realizing those benefits depends on farmers knowing how to configure the technology, plan their season, and adjust their practices as conditions change.
John Deere deployed OpenAI’s APIs to help make that support personalized and scalable.
AI can answer farmers’ questions in natural language, provide tailored setup guidance and recommendations, identify when equipment may not be delivering its full potential, and help farmers understand the value they’re getting from the technology.
The opportunity extends beyond any single interaction: to deliver relevant guidance throughout the customer journey, helping farmers make better use of their equipment while improving efficiency and sustainability.
This is the kind of challenge OpenAI FDEs work to solve: helping organizations move from AI capabilities to systems that deliver practical value in complex, real-world environments.
But the problems are often wide open, there may be no established ground truth, and there is no playbook. Everyone wants to build something that has never existed. Fewer people want to do what it takes to get there.
Finding talented FDEs while raising the baseline for “good enough” has meant constant experimentation and application.
Start with the outcome
At the start of every FDE team session, I put up a slide with one core value: “Start with the outcome, do what it takes to succeed, then follow with scale”.
An impressive demo can go a long way before anyone asks whether it works in the real world.
Our job is to solve the customer’s problem to a standard we can stand behind in production.
In mid-2025, we had around 15 FDEs working with a large semiconductor customer on 10+ use cases. The ambition was to make their verification process AI-native, covering:
- Directed test generation
- Root cause analysis and debugging
- An architecture assistant
Verification can account for ~70% of a project’s effort in this industry. The opportunity was enormous, and there were many possible places to start.
Some FDEs had joined OpenAI just days earlier and had never worked in semiconductors. They embedded with the customer’s verification team, studied chip design in their spare time, and built evals with the engineers to test whether the AI could generate useful tests and correctly diagnose chip failures.
Alongside that learning, we built custom harnesses for the individual use cases. Over the first 3-6 months, all of them reached production and early user adoption. The payoff was seeing the metrics:
- ~48% time saved through AI-based directed test generation.
- 22% median performance improvement through kernel optimisation.
- Weeks of debugging compressed into hours
When we played this all back the Chief Hardware Officer asked, “Did you guys work as chip designers before coming here?”
Our FDEs don’t need to know the industry on day one but it is their responsibility to learn it.
As coding assistants make software faster to build, understanding the customer’s business becomes even more important. We build teams with a mix of generalists and domain experts.
You need enough knowledge to make sound judgments, and enough curiosity to question assumptions about the status quo.
In life sciences, for example, our FDEs’ scientific backgrounds help them earn trust with researchers working on pre-clinical drug discovery tasks such as target validation and prioritization, gene-expression analysis, and chemical synthesis-route reconstruction. That expertise lets them contribute informed judgment about how those workflows could improve.
Make success repeatable
We had shown that these workflows could deliver value, but each still required too much custom integration to extend to another team. The next challenge was to preserve those results while making the software easier to deploy and maintain.
By then, Codex had grown in capability. One FDE tested rebuilding their application around it, then worked with the team to move the use cases onto a common harness with Codex at its core.
Custom applications became plugins and skills built on common Codex primitives. Codex also became the interface, allowing us to retire the separate terminal UIs and CLIs we had written for individual use cases.
We were able to remove roughly 90% of the custom code from each project, and this changed how we built, maintained and scaled these workflows:
- We could benefit from centralized improvements to Codex, reducing the amount of glue code required for each individual use case
- Key functionalities were bundled as skills and plugins, making them easier to share with each other and to be centrally controlled by the AI CoE. This meant that extending from one team to the next could be as simple as swapping in new connectors/MCP servers, building fresh evals (which we also had a skill for) and getting up and running.
- In one August 2026 example, the initial deployment took two months. Extending the solution to a second team took one day. The next teams onboarded faster as we scaled—this has continued, with a use case in August 2026 taking 1 day for the second team after the initial deployment took 2 months.
That is one version of making ourselves obsolete. The work we had done to reach production established what mattered. As the underlying product improved, we could replace much of our custom implementation and keep the value it delivered.
This is why the order matters. LLMs let us build fast. Use that speed to get something valuable into users’ hands, learn what holds up in practice, and then scale what works.
The same principle applies across all engagements.
OpenAI Presence, our product for enterprise voice and chat agents, grew out of real customer deployments. The work began with Swarm(opens in a new window) and evolved through the Agents API, and today one customer now handles more than half of its calls with AI.
Getting those deployments into production taught us which problems needed a custom solution and which building blocks other teams could use. We brought those building blocks into Presence, making it easier for developers to automate regulated workflows without rebuilding the underlying infrastructure. Each deployment helped shape the product and gave the next customer a better starting point.
With Thrive Holdings, OpenAI FDEs and researchers worked alongside engineers and accountants to build Tax AI for Crete’s accounting firms. During its pilot, Tax AI processed 7,000 tax returns and increased throughput by about 50%.
One of the hardest challenges was automating rental-property returns, which required six weeks of engineering and practitioner review to reach 90% precision and recall. The work created reusable patterns that made it easier to extend Tax AI to other complex tax schedules.
The teams are now applying the same approach to bookkeeping, audit, and IT support—building systems that improve through practitioner feedback and real-world use.
Close the intelligence gaps as they appear
Sometimes a better product lets us simplify what we built but sometimes the model itself cannot yet do the job.
If we only build what today’s models already make possible, we will not uncover the intelligence gaps Research needs to close next. Therefore a lot of our important engagements start at those limits with the customer, FDE and Research committed to working through them together.
We had already developed a customer-service platform with a large telecommunications customer, and they wanted to extend it to voice.
Voice accounted for around 90% of their customer-service volume. These cases were more expensive to contain than chat, and brought a range of new technical challenges in getting accents, tone and latency/accuracy up to production grade. Getting it right would make a substantial difference to their business.
During scoping, our model scored around 60% on the key evals we used to assess whether it could do the job in production. We had reached the limits of its capabilities. Function calling and instruction following in customer-service scenarios needed to improve.
We explained that to the customer and brought Research into the work. FDE worked with the customer to build the platform and define what the model needed to do. Research worked on closing the capability gaps, with successive model snapshots letting us test progress against the customer’s requirements.
Over six months, performance on the key evals rose from around 60% to 80% and then 90%+, reaching the levels needed for production.
The resulting voice model now supports that customer’s deployment, other custom customer-service deployments, and managed deployments through Presence. A problem encountered in one customer’s business helped identify improvements that could serve many others.
Each part mattered. The customer committed to working on a problem the model could not yet solve. FDE stayed close enough to frame that problem, build the platform and drive the engagement from start to finish. Research improved the underlying model capabilities.
This is the other version of making ourselves obsolete: helping turn a problem today’s models cannot solve into a capability future models can deliver. The return on our work extends beyond the hours we spend with any one customer.
Go find the harder problem
I joined OpenAI to help make AI useful in people’s everyday work. That still guides the team. I often say to the team that in most cases in LLM development, Occam’s Razor applies—the simplest solution is the best. In a company that is defined by its cutting edge research and in an industry that is tainted by hyperbole, we want to build stuff that works reliably which people in the field can depend on.
The goal is for each engagement to improve what comes next: a product that is easier to deploy, a model that can handle a harder task, or less custom work for the next customer.
If you have a hard problem you want to solve, we’d love to work with you. If you want to help solve those problems, we’d love you to join us.
So what do we do when Codex can handle the work we spent months building?
Go find the harder problem.